Have you ever opened an application and thought:
“Why is this page taking forever to load?”
Sometimes the problem isn't the frontend.
It isn't the API.
And it isn't necessarily your server either.
The real problem might be hiding inside your database query.
Imagine you have a table containing one million users. Then you run a query like:
SELECT * FROM users WHERE email = 'user@example.com';Without a proper index, the database may need to check a large number of rows to find the matching record.
That can become painfully slow as your data grows.
This is where database indexing comes in.
A database index is one of the most important tools for improving database performance, especially when your application starts handling thousands or millions of records.
But what exactly is an index?
And why can it make a query dramatically faster?
Let's break it down in simple terms.
What Is Database Indexing?
Database indexing is a technique used to help a database find data faster.
Think about a physical book.
Imagine you want to find information about “database indexing” in a 500-page technical book.
Without a table of contents or index, you might have to flip through the pages one by one.
That's basically what a database may have to do when it doesn't have a suitable index.
Now imagine the book has an index at the back:
Database indexing — pages 120, 145, 210
You can jump directly to the relevant section.
A database index works in a similar way.
Instead of searching through every row in a table, the database can use an index to quickly locate the rows that match your query.
A Simple Example
Suppose we have a users table:
id | name | city | |
|---|---|---|---|
1 | Andi | Bandung | |
2 | Sarah | Jakarta | |
3 | Rizal | Bandung | |
... | ... | ... | ... |
1,000,000 | User | Jakarta |
Now imagine we frequently run:
SELECT * FROM users
WHERE email = 'rizal@example.com';
Without an index on email, the database may have to inspect many rows to find the correct record.
With an index:
CREATE INDEX idx_users_email
ON users(email);
the database has an additional structure that helps it locate matching values much more efficiently.
The result?
Faster queries.
How Does a Database Index Actually Work?
This is where things get interesting.
Most relational database systems use data structures such as B-tree indexes for many common indexing operations.
You don't necessarily need to understand every internal detail, but understanding the basic idea is useful.
Imagine the database has 1,000,000 records.
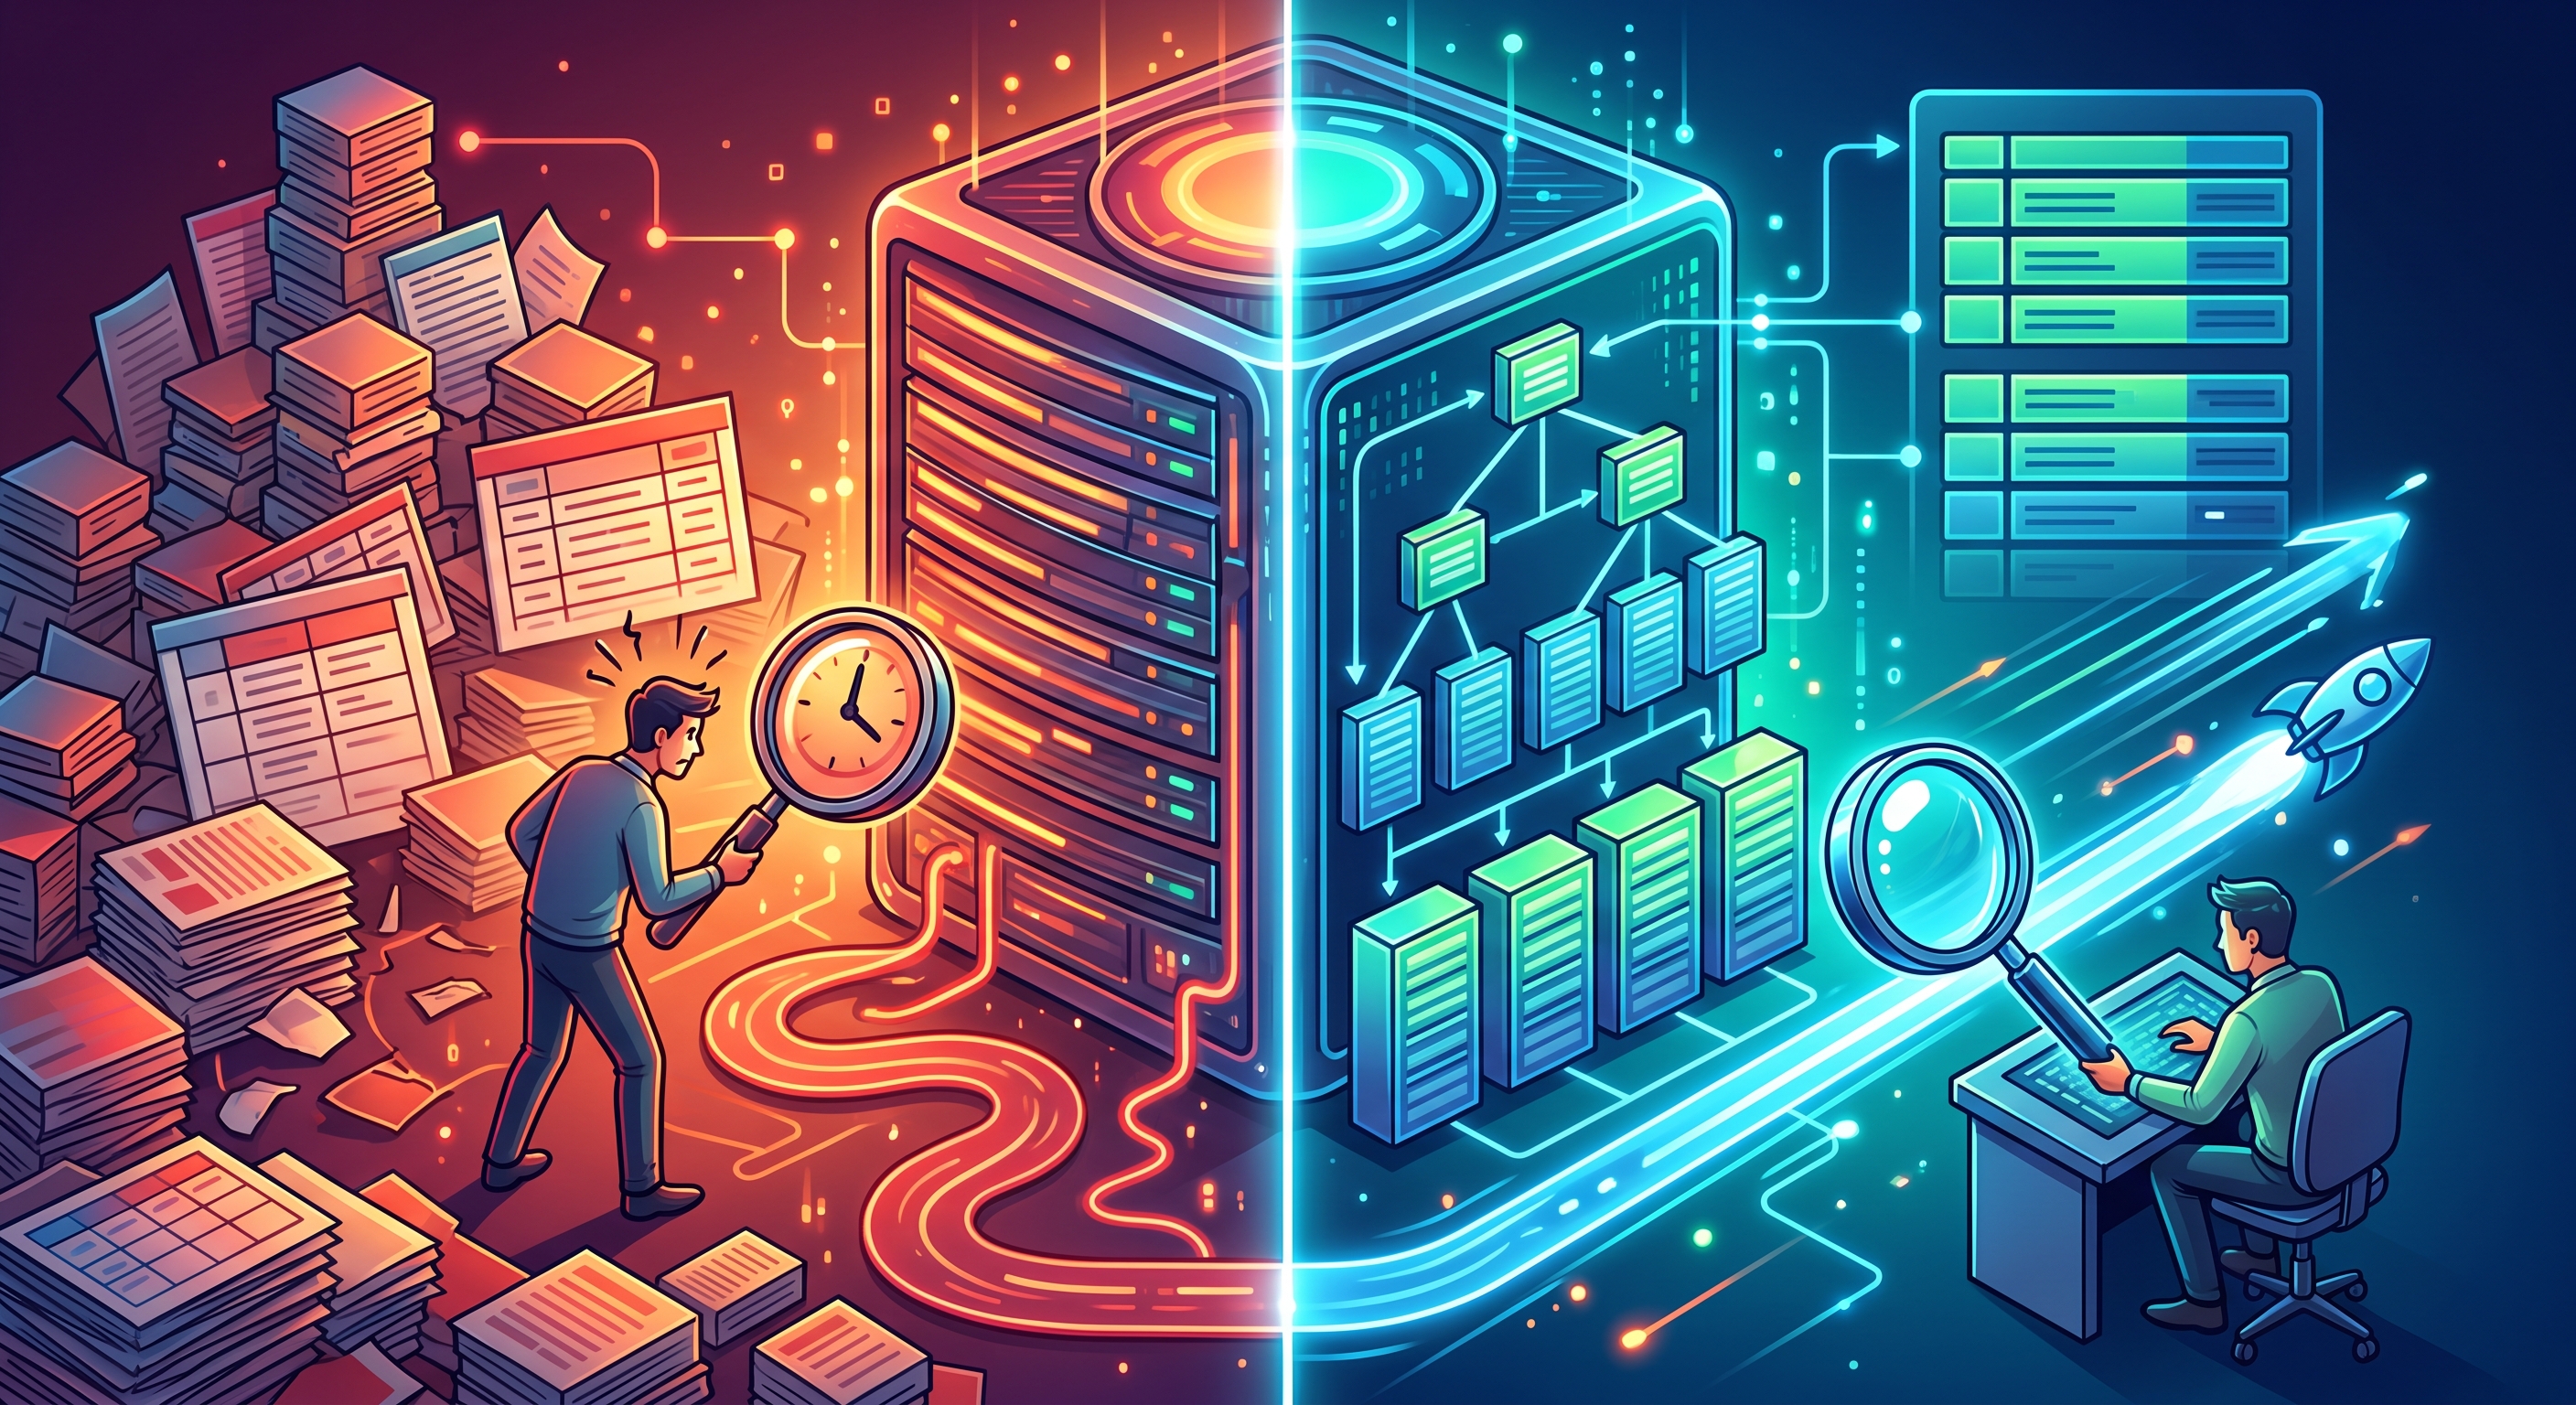
Without an index, the database might need to scan a large portion of the table.
With an index, the database can navigate through the index structure to narrow down the search much more quickly.
Conceptually, instead of doing something like:
Row 1 → Row 2 → Row 3 → Row 4 → ... → Row 1,000,000
it can perform a much more efficient lookup through the index structure.
This is one reason indexes can dramatically improve query performance.
What Is a Table Scan?
When a database checks rows across a table to find matching data, this is commonly referred to as a table scan or full table scan, depending on the database system and execution plan.
For a small table, this may not be a big deal.
Imagine a table with only 100 rows.
Scanning 100 rows is trivial.
But what happens when your table grows to:
100,000 rows?
1 million rows?
10 million rows?
Now the amount of data that needs to be examined can become significant.
This is why indexing becomes increasingly important as applications grow.
Why Does Indexing Make Queries Faster?
The basic reason is simple:
An index reduces the amount of data the database needs to examine.
Suppose your table contains 5 million rows.
Your query only needs one record.
Searching all 5 million rows would be inefficient.
An appropriate index gives the database a much better path to the required data.
This can significantly reduce:
Query execution time
CPU usage
Disk I/O
Database workload
Application response time
And when your application receives many requests at the same time, these improvements can become even more noticeable.
Primary Key Is Usually Indexed
One important thing to understand is that primary keys are commonly indexed automatically by relational database systems.
For example:
CREATE TABLE users (
    id BIGINT PRIMARY KEY,
    name VARCHAR(100),
    email VARCHAR(255)
);
The id column is typically indexed because it is the table's primary key.
That's why a query like:
SELECT * FROM users
WHERE id = 500000;
can usually be handled efficiently.
But that doesn't mean every column should be indexed.
And that's where things become more interesting.
Should You Index Every Column?
No.
Adding indexes everywhere sounds like a great idea at first.
More indexes = faster queries, right?
Not exactly.
Indexes come with costs.
When you insert, update, or delete data, the database may also need to update the relevant indexes.
For example, imagine a table with 10 indexed columns.
Every time you insert a new row, the database may need to update all of those index structures.
That means additional work.
Indexes also consume storage space.
So the goal isn't:
“Create as many indexes as possible.”
The goal is:
“Create the right indexes for the queries your application actually runs.”
When Should You Create an Index?
Indexes are especially useful for columns that are frequently used in:
WHERE Clauses
SELECT * FROM users
WHERE email = 'user@example.com';
An index on email can help this query.
JOIN Conditions
For example:
SELECT *
FROM orders
JOIN users
ON orders.user_id = users.id;
Indexes on columns involved in joins can improve query performance.
ORDER BY
For example:
SELECT *
FROM products
ORDER BY created_at DESC;
Depending on the database and query pattern, an appropriate index can help with sorting and retrieval.
GROUP BY
Indexes may also help certain aggregation and grouping operations, although the actual benefit depends heavily on the query and database optimizer.
What Is a Composite Index?
Sometimes your query uses multiple columns.
For example:
SELECT *
FROM orders
WHERE user_id = 100
AND status = 'completed';
Instead of creating two separate indexes, you might consider a composite index:
CREATE INDEX idx_orders_user_status
ON orders(user_id, status);
This index contains multiple columns.
But there's an important concept to understand:
Column Order Matters
A composite index on:
(user_id, status)is not necessarily equivalent to:
(status, user_id)The order of columns can affect which queries can use the index effectively.
That's why composite indexes should be designed based on actual query patterns rather than guesswork.
What Is a Unique Index?
A unique index ensures that values in a column, or combination of columns, remain unique.
For example:
CREATE UNIQUE INDEX idx_users_email
ON users(email);
Now two users can't have the same email address, assuming the database's uniqueness rules permit that behavior for the relevant data type and null semantics.
This is useful for fields such as:
Email addresses
Usernames
Employee numbers
Account identifiers
A unique index can provide both data integrity and efficient lookup.
Database Indexing and Query Optimization
Creating an index doesn't automatically guarantee that every query will become faster.
Modern databases use a query optimizer to decide how a query should be executed.
The optimizer may choose:
An index scan
A table scan
A different index
A join strategy
Another execution plan
depending on the data and query.
This is why developers should inspect query execution plans when optimizing slow queries.
In many SQL databases, you can use commands such as:
EXPLAINor database-specific variations such as:
EXPLAIN ANALYZEThese tools can help you understand how the database is executing your query.
Example: Before and After Indexing
Imagine we have:
SELECT *
FROM orders
WHERE customer_id = 12345;
The orders table contains 5 million records.
Without an index on customer_id, the database may need to inspect a large portion of those rows.
Now create:
CREATE INDEX idx_orders_customer_id
ON orders(customer_id);
The database now has a structure that can help locate orders for customer 12345 much more efficiently.
The actual performance improvement depends on many factors, including:
Table size
Data distribution
Query structure
Database engine
Hardware
Cache
Existing indexes
Selectivity of the indexed column
So it's better not to think of indexing as a magic “10x faster” button.
Think of it as giving the database a better way to find the data it needs.
The Problem With Low-Selectivity Columns
Not every column benefits equally from an index.
Consider a users table with:
genderSuppose almost every row contains one of only a few possible values.
An index on such a low-selectivity column may provide limited benefit for some queries because the database still has to process a large portion of the matching rows.
Compare that with:
emailwhere values are typically much more unique.
This is one reason selectivity matters when designing indexes.
Too Many Indexes Can Hurt Performance
Here's another common mistake:
“The query is slow, so let's add another index.”
Sometimes that works.
Sometimes it makes things worse.
Too many indexes can:
Consume more disk space
Increase write overhead
Slow down INSERT operations
Slow down UPDATE operations
Slow down DELETE operations
Make database maintenance more expensive
In other words:
Indexes speed up some reads by adding work to writes.
That's the trade-off.
Indexing in Real-World Applications
Let's say you're building an e-commerce application.
You have:
users
products
orders
order_items
payments
You might frequently query:
SELECT * FROM orders
WHERE user_id = 123;
You might also query:
SELECT * FROM products
WHERE category_id = 10
AND status = 'active';
And:
SELECT * FROM orders
WHERE created_at >= '2026-01-01'
ORDER BY created_at DESC;
Instead of randomly adding indexes everywhere, look at your application's real query patterns.
Ask:
Which queries run frequently?
Which queries are slow?
Which columns appear frequently in
WHERE?Which columns are used in joins?
Which columns are commonly used for sorting?
How large is the table?
How often is the data written?
That's how good indexing decisions are made.
Common Database Indexing Mistakes
1. Indexing Everything
More indexes don't automatically mean better performance.
2. Never Checking Query Performance
Don't guess.
Measure.
Use execution plans and application monitoring to identify real bottlenecks.
3. Ignoring Composite Index Column Order
A multi-column index should be designed around actual query patterns.
4. Forgetting About Write Performance
Indexes help reads, but they also need to be maintained when data changes.
5. Keeping Unused Indexes
An index that is rarely or never used may simply add maintenance cost without providing meaningful value.
A Simple Mental Model
Here's an easy way to remember how indexing works:
No index:
“Search the whole warehouse until you find the product.”
With index:
“Check the catalog, go directly to the right shelf, and get the product.”
The database still has work to do.
But it has a much better map.
Final Thoughts
Database indexing might sound like a low-level technical detail, but it can have a huge impact on application performance.
When your application has only a few hundred records, you may not notice much difference.
But as your database grows to hundreds of thousands or millions of rows, inefficient queries can become a serious performance problem.
The key lesson is:
Don't create indexes simply because indexes are supposed to be fast. Create them because your application's actual query patterns justify them.
Good indexing is about balance.
You want faster reads without creating unnecessary write overhead, storage costs, and maintenance complexity.
So the next time you find yourself staring at a slow SQL query, don't immediately rewrite the entire application.
Start by asking:
“Does the database have a good path to the data I'm asking for?”
Sometimes, the answer is simply...
Add the right index.
Read other articles